Introduction
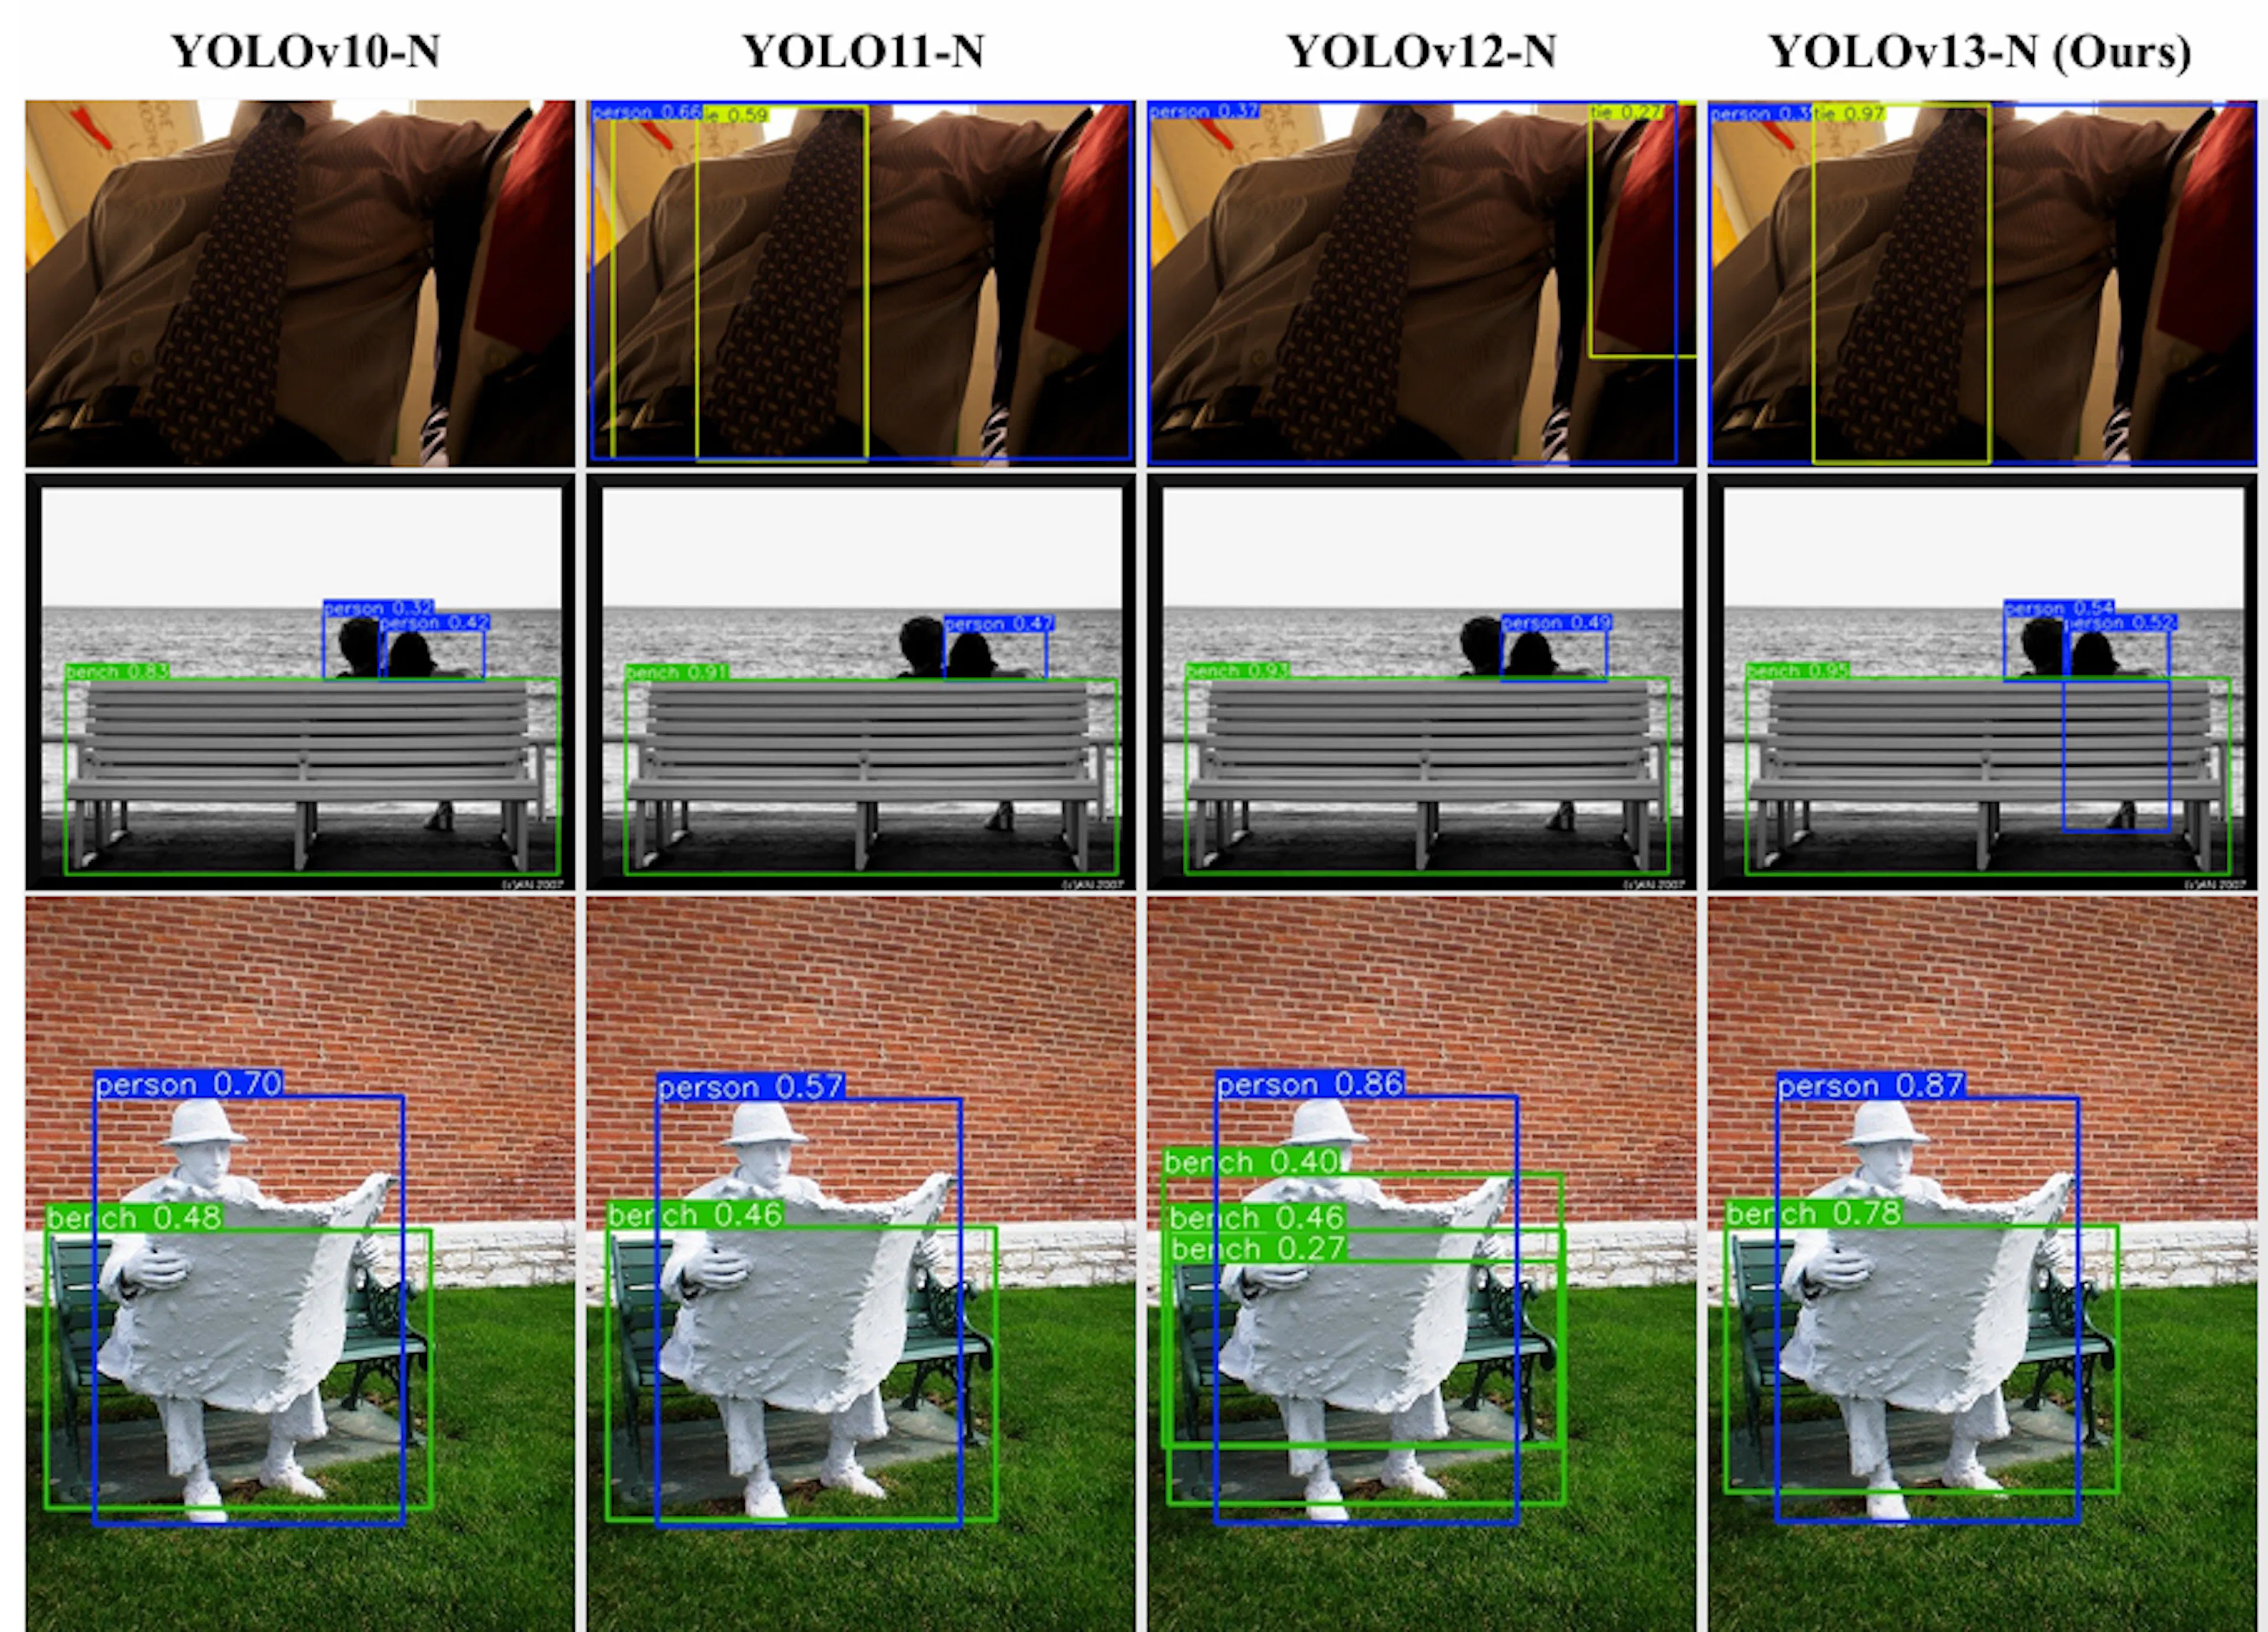
Vision-Language Models (VLMs) represent a significant advancement in artificial intelligence, merging computer vision with natural language processing to enable machines to interpret and generate content based on both images and text. Unlike traditional AI models that handle one modality at a time, VLMs integrate visual understanding with linguistic fluency, allowing for more nuanced interaction with multimodal data.
What Happened
For years, AI systems were specialized - some could classify images, others could generate text, but few could do both simultaneously. The rise of large language models shifted the landscape, prompting researchers to explore whether models could process visual inputs alongside language. This exploration gave birth to Vision-Language Models, which fuse visual perception with textual reasoning, creating systems that can see and speak about content simultaneously.
Why This Matters
The ability to ground language in visual reality opens new possibilities for human-computer interaction, accessibility, and intelligent search. VLMs move beyond abstract text patterns by connecting words to actual pixels, enabling tasks like image description, visual reasoning, and multimodal search. This integration represents a step toward AI that can perceive and communicate about the world more like humans do.
Key Takeaways
- Integrated architecture: VLMs fuse image encoders with language models via a projection layer that aligns visual features with text embeddings.
- Data dependence: High-quality, aligned image-text pairs are expensive and difficult to curate, making dataset quality the primary determinant of model performance.
- Practical applications: Real-world uses include image captioning, visual question answering, and multimodal search, each demonstrating value across different sectors.
- Open challenges: Model complexity, bias, limited reasoning, hallucination, poor generalization to unfamiliar data, and high computational costs remain significant hurdles.
- Future trajectory: Despite limitations, VLMs are advancing toward AI that can genuinely see, understand, and describe visual content in ways that mimic human intuition.
Conclusion
Vision-Language Models are more than a technical mashup - they represent a meaningful step toward AI that can perceive, interpret, and communicate about the world in a more integrated, human-like way. As the technology matures, broader adoption across industries and continued refinement in how machines bridge the gap between sight and language are expected.


Discussion
Join the conversation
Thoughtful reactions, questions, and follow-up ideas help shape the next story.